Create Your Tests Using Your Favorite AI Agent
Point Claude Code, Codex, or Cursor at your app. It writes test-lab plans grounded in your code, or converts the tests you already have, then ships them in one command.

Point Claude Code, Codex, or Cursor at your app. It writes test-lab plans grounded in your code, or converts the tests you already have, then ships them in one command.

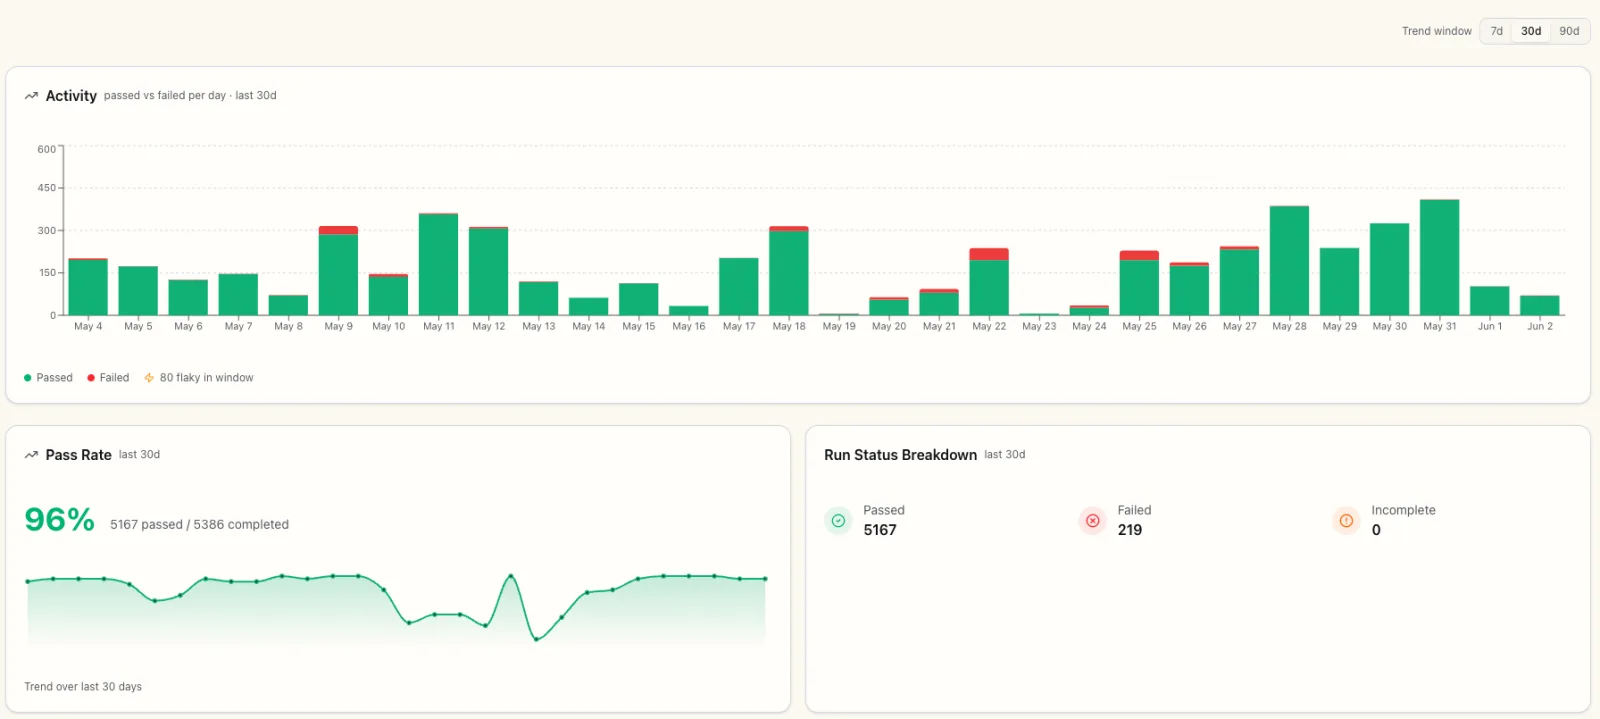
Click into the real test-lab.ai admin without an account. Browse example test plans, open real run reports, and see the CI setup we run on every deploy, most of it cheap Playwright script runs.

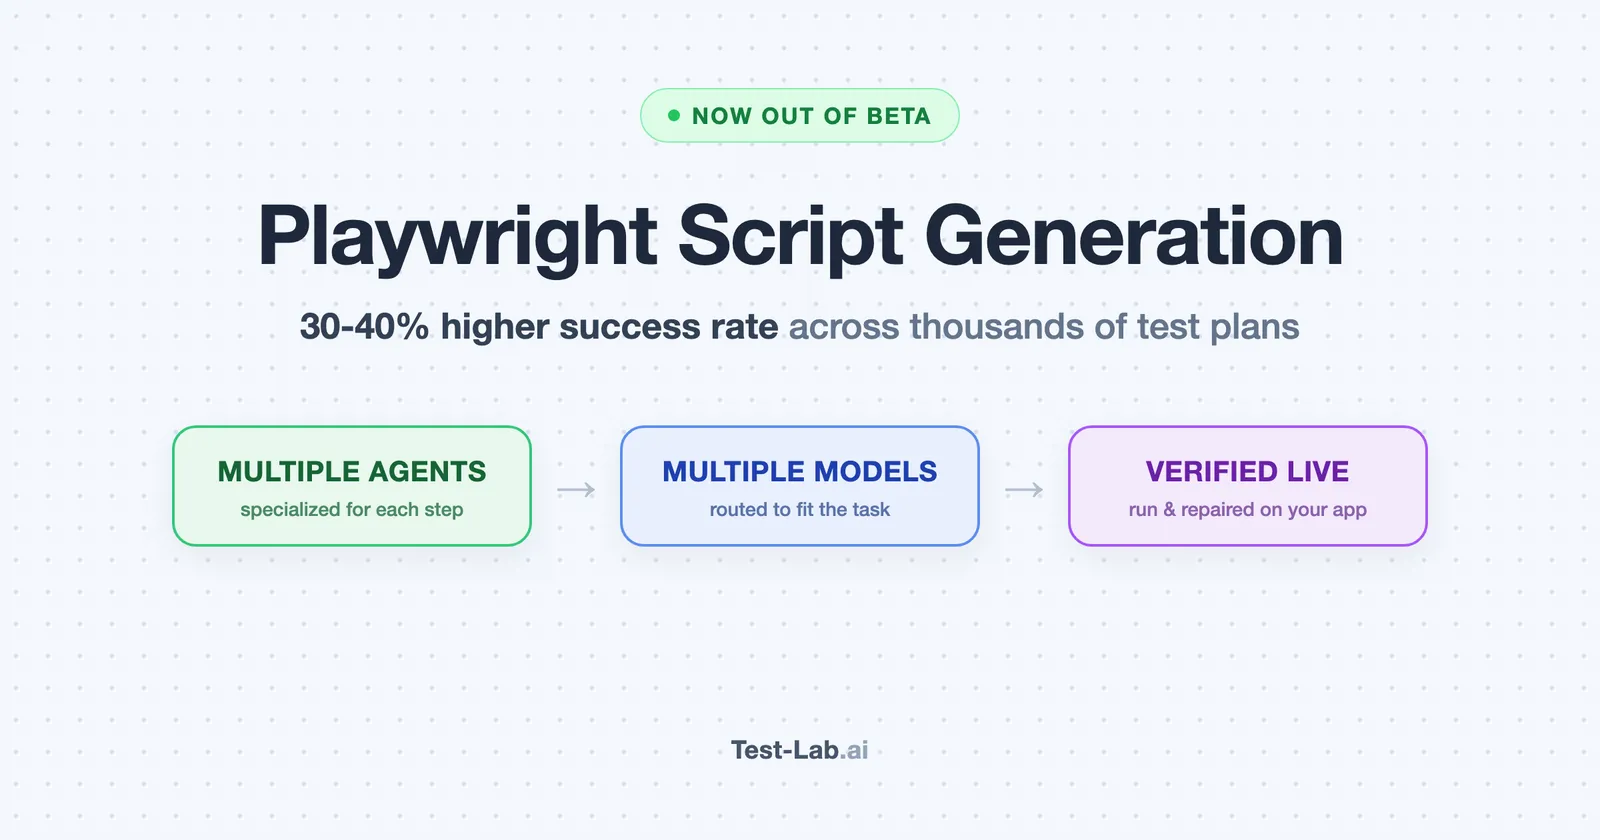
Test-Lab's AI Playwright script generation is leaving beta. After thousands of real test plans, a pipeline of specialized agents over multiple models lifted clean-script success by 30 to 40 percent. Here is what changed and what you get today.

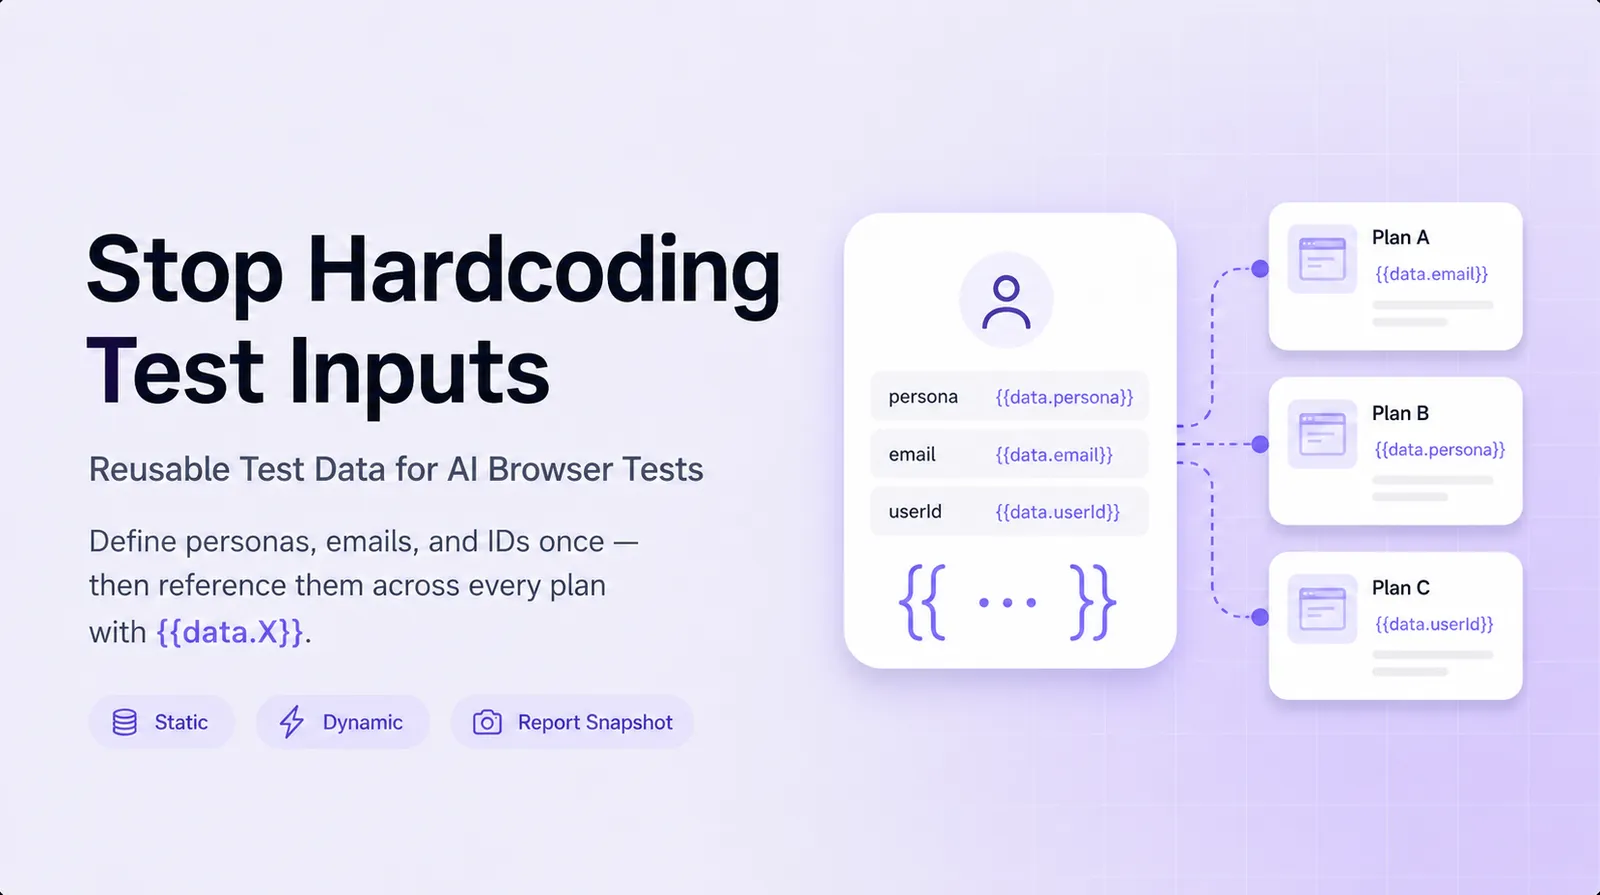
Define test personas, emails, and IDs once and reference them across every plan with {{data.X}}. Static for stability, Dynamic for per-run uniqueness, pipeline-shared values for multi-step flows, frozen snapshots in every run report.

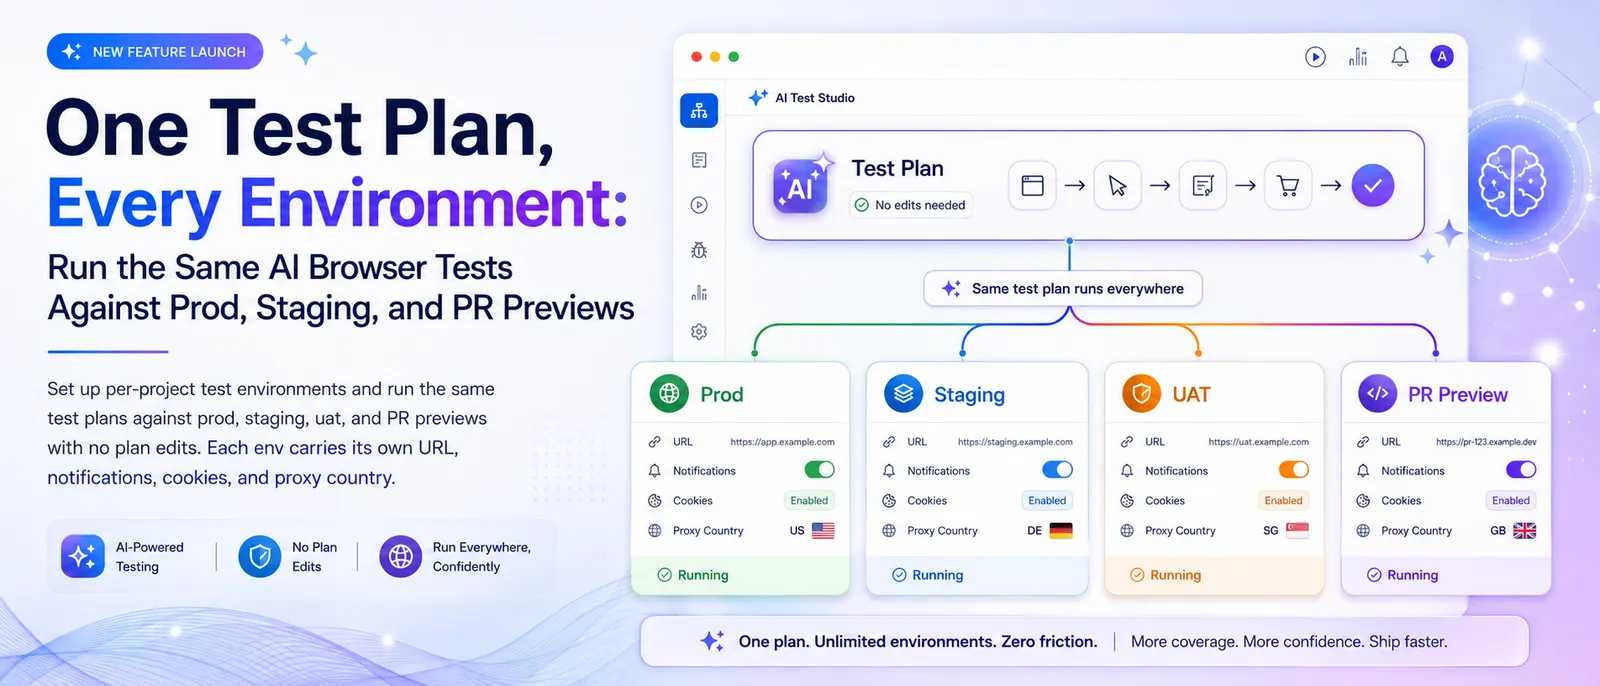
Set up per-project test environments and run the same test plans against prod, staging, uat, and PR previews with no plan edits. Each env carries its own URL, notifications, cookies, and proxy country.

We ran Claude Opus 4.7 and OpenAI GPT-5.5 through the same Playwright script generation pipeline across hundreds of generation cycles. Here is what the data says about speed, cost, and reliability for AI-driven E2E test authoring.

Anthropic shipped Claude Opus 4.7. OpenAI shipped Codex 5.5. We've been building Test-Lab features with both for the last few weeks. Here is what actually changed, where each one shines, and how the new design and image features fit in.

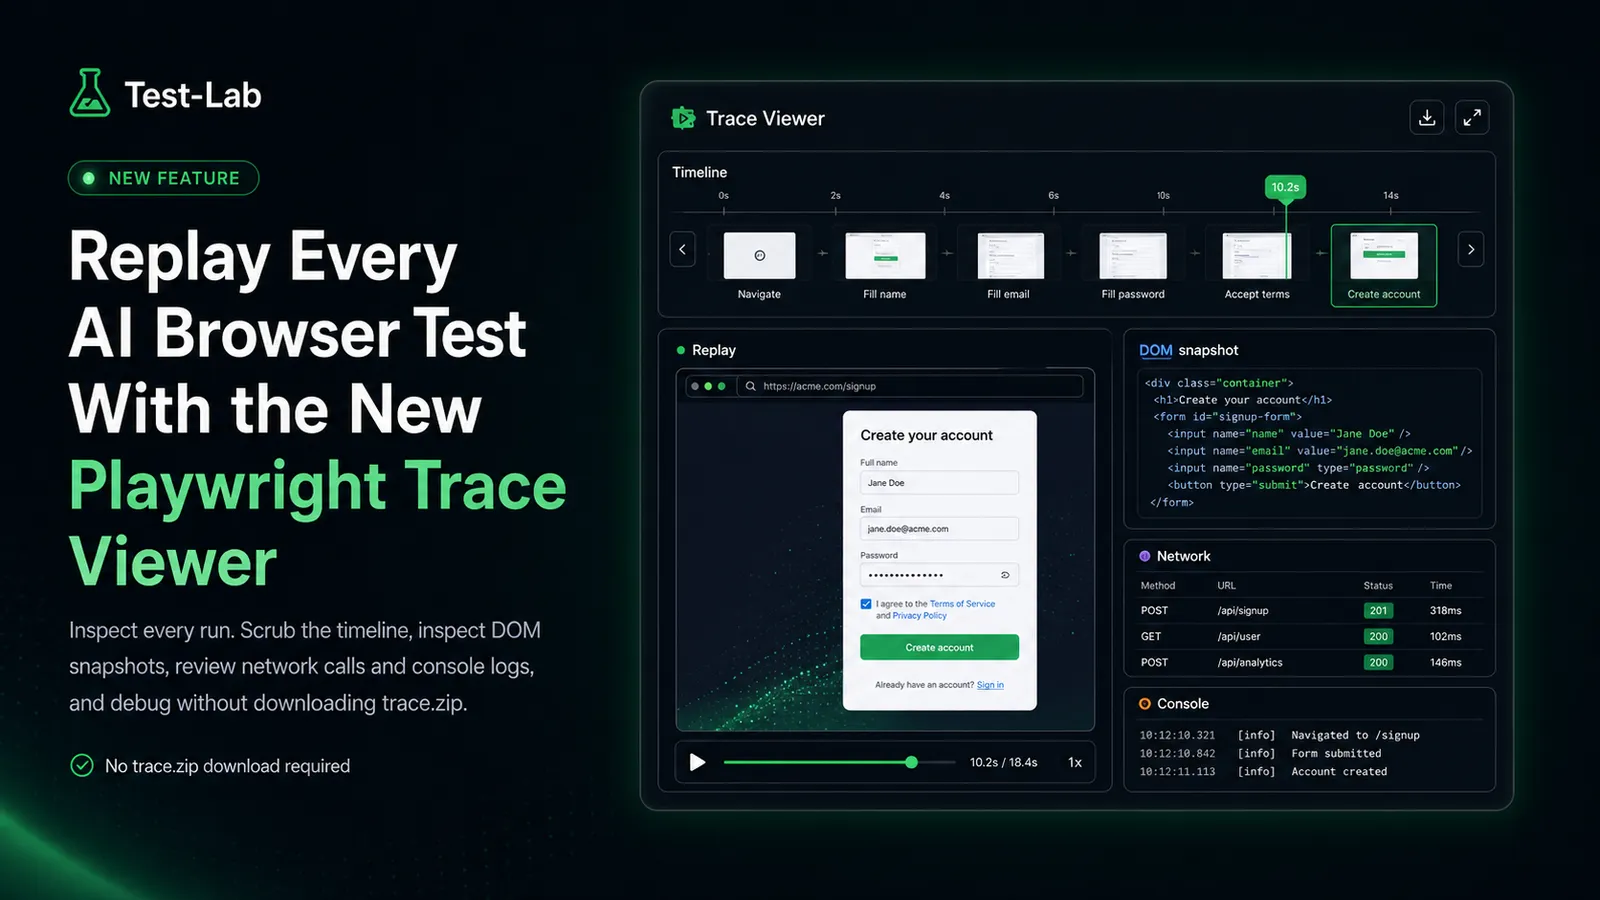
Replay any AI browser test run inside Test-Lab with the embedded Playwright trace viewer. Walk the action timeline, inspect DOM snapshots, network calls, and console logs without ever downloading a trace.zip.

Generate real Playwright tests from one AI run, heal them when the UI shifts, refine them with chat. A practical fix for flaky tests at a fraction of the cost of running AI on every CI build.

We ran 11 frontier models against the same hardened production plan through our internal benchmarking harness. Here are the pass rates, durations, and costs that matter for AI driven browser automation.